
SpeechData.ai Review: Conversational Speech Datasets in 60 Languages
OtherDescription
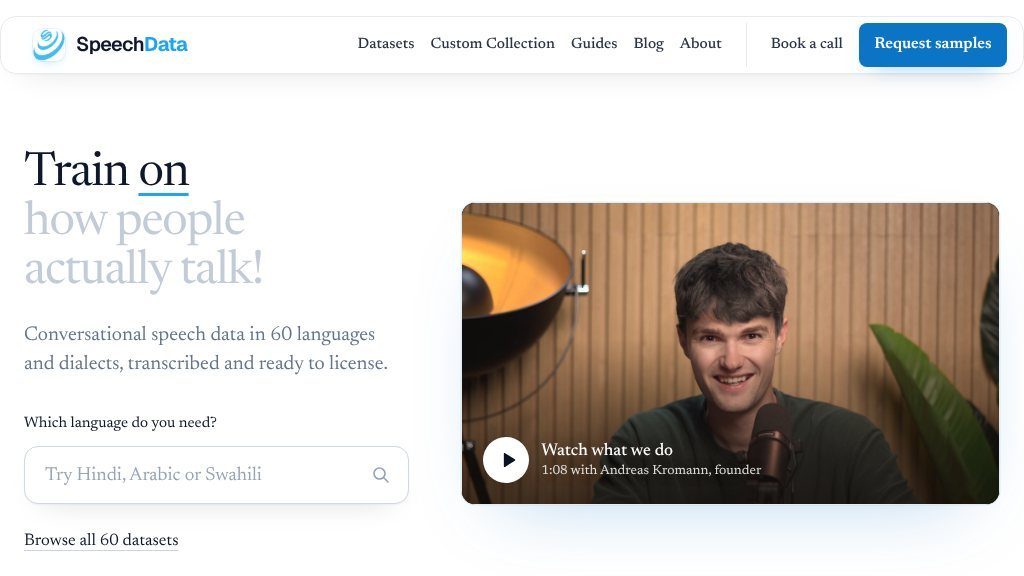
License off-the-shelf conversational speech datasets in 60 languages and dialects: hours of transcribed, consented, metadata-rich audio from vetted native speakers.
The Main Idea
Teams building or evaluating automatic speech recognition, voice, and multilingual AI systems often need to decide whether existing audio data is realistic enough for production use. SpeechData.ai focuses on that decision by offering off-the-shelf conversational speech datasets in 60 languages and dialects. The listed collections contain recorded conversations rather than read scripts, with transcriptions and speaker metadata intended to support model training, filtering, and evaluation.
The visible site information describes the data as consented, commercially licensable, and collected from vetted native speakers. Dataset pages show different language and regional options, along with the available audio hours, speaker count, transcription status, and per-hour price.
What Visitors Can Explore
The catalog covers eight broad regions, including Europe, South Asia, Southeast Asia, East Asia, the Middle East, Africa, North America, and Latin America. Examples shown on the site include US English, Latin American Spanish, Hindi, Taiwanese Mandarin, Modern Standard Arabic, and Swahili. The broader coverage also mentions languages such as Yoruba, Amharic, and Moroccan Darija, as well as multiple Arabic and Indian language variants.
Featured datasets are described as spontaneous, two-person conversations with natural disfluencies, turn-taking, and code-switching. The supplied metadata includes time-aligned transcripts and speaker details such as age, gender, region, and recording device. The site also describes dual-channel recordings and quality checks, although visitors should review sample files and documentation to confirm that a specific dataset meets their technical requirements.
Strengths
- Coverage across 60 languages and dialects, including less commonly served regional varieties
- Conversational recordings with transcripts, speaker metadata, and stated dual-channel capture
- Commercial-use consent documentation is described as part of the data offering
- Samples and published per-hour pricing support an initial data-quality and budget review
Cons
- Dataset depth, speaker diversity, and technical specifications may vary by language and require individual verification
- The visible information does not fully detail file formats, delivery methods, or licensing terms for every collection
- Pricing and custom-collection scope may require confirmation for volume or multi-language purchases
Potential Uses
This type of data may be relevant for training or testing speech recognition models, especially where scripted recordings do not reflect everyday conversation. It could also help teams create language-specific evaluation sets, compare regional speech patterns, or filter data by speaker and recording characteristics.
The listed pricing ranges from $60 to $95 per hour of audio, depending on the language. Free samples are available to inspect audio quality, transcript accuracy, and speaker diversity before licensing. Custom collection is also presented as an option for languages, dialects, or domains not already stocked.
Audience and Fit
SpeechData.ai appears most suited to AI teams, research groups, and developers who need multilingual conversational audio with accompanying transcripts and documentation. It may be less relevant for buyers seeking general voice recordings, text-only corpora, or a self-service annotation platform.
Before You Rely on It
The catalog provides useful headline details, but buyers should verify licensing terms, consent records, file formats, transcript quality, dialect balance, speaker overlap, and delivery process for the exact dataset under consideration. Published prices may also change or vary with volume and multilingual orders. A practical evaluation is to compare the available samples against the acoustic conditions and language varieties your model will encounter.
Embeds
Copy short script widgets for this listing. People often use Textfrog to search for their next personal or work tool. Encourage your community to leave reviews on Textfrog.
Review widget
A clean review badge with stars and review count.
Featured badge
A compact badge for products listed on Textfrog.
Similar Tools
Choose a hand and get three complete palm line readings free from one private ph...
Use a free tarot birth card calculator to find your Major Arcana card pair from ...
Discover the perfect hotels for your next adventure and read authentic reviews f...
Add, subtract, multiply, or divide fractions and see how the answer is made. wit...
Featured Links
Setvo: your workouts, your progress, your space. with practical details for onli...
Eduify is an online education platform that provides tools and resources for lea...